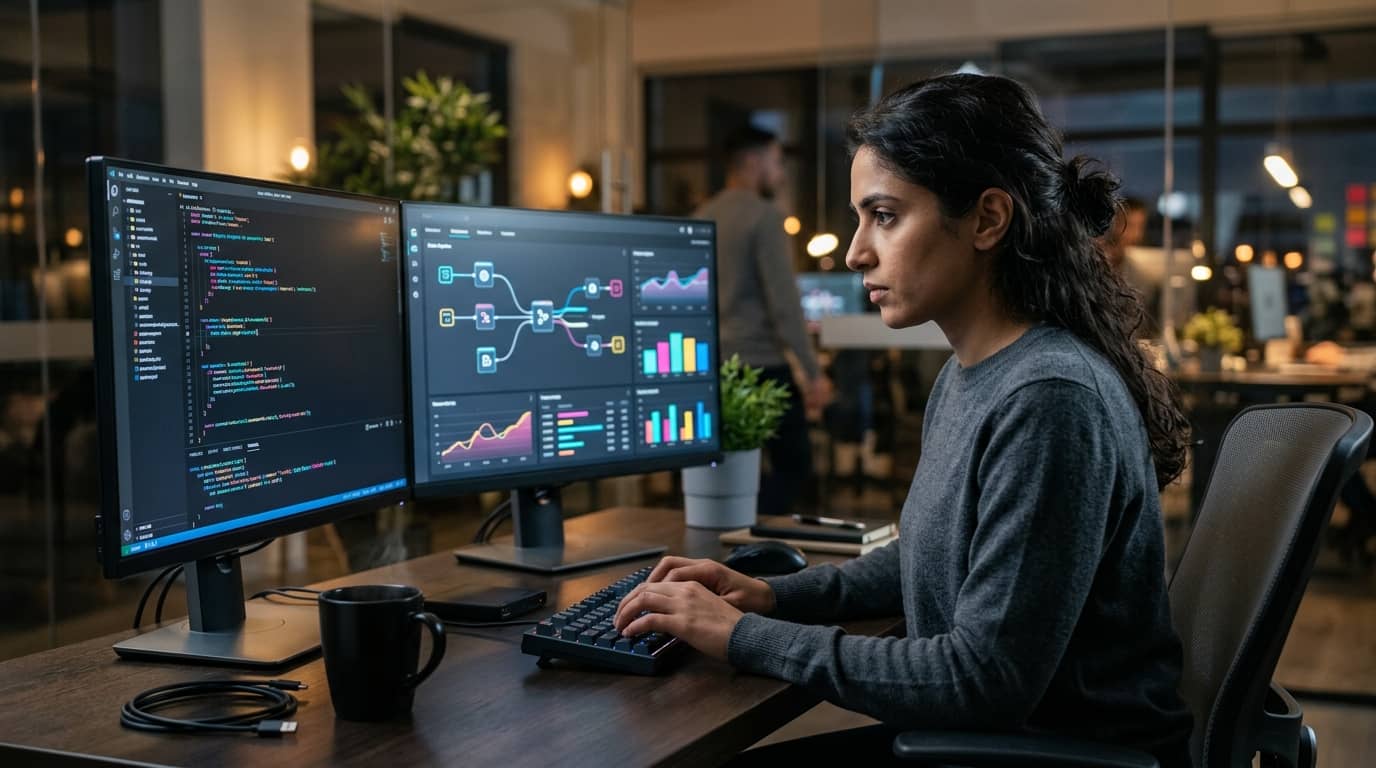
Azure Databricks Course
Master Azure Databricks from the ground up and build production-grade data pipelines, streaming solutions, and machine learning workflows on the Azure cloud. This course covers Delta Lake, Unity Catalog, Structured Streaming, and MLflow in hands-on depth. Whether you're moving into data engineering or levelling up your current skills, this is the complete Databricks training you need.
What you'll learn:
You will learn how to configure Azure Databricks workspaces, write optimised Apache Spark code, and build reliable ETL pipelines using Delta Lake and Auto Loader. The course covers Structured Streaming for real-time data processing, Unity Catalog for enterprise governance, and Databricks SQL for analytical workloads. You will also implement the full machine learning lifecycle using MLflow, the Feature Store, and Databricks Model Serving. Production topics include CI/CD integration, cost management, security configuration, and disaster recovery. By the end, you will have the skills to design and operate scalable data platforms on Azure Databricks.
How you study in practice Azure Databricks Course
How you practise Azure Databricks Course
For businesses looking to train their team
With Elevify for businesses, the course includes exercises and examples tailored to your own business and the way your company needs.

Course content
8 Chapters • 40 LessonsDuration between 4 and 360 hours (you decide)
Chapter 1HideHide detailsSee detailsAzure Databricks Foundations and Setup
Azure Databricks Foundations and Setup
Lesson 1 • Notebooks and Collaboration
Introduces Databricks notebooks as the primary development interface for code and documentation. Covers multi-language support and real-time collaboration features.
Lesson 2 • Clusters: Types and Configuration
Explains all-purpose and job clusters, their configuration options, and cost implications. Students create and manage clusters to run workloads efficiently.
Lesson 3 • Databricks CLI and REST API Basics
Introduces programmatic access to Databricks through the CLI and REST API for automation. Connects workspace management to scripting and DevOps workflows.
Lesson 4 • What Is Azure Databricks
Covers the origin, purpose, and key capabilities of Azure Databricks as a unified analytics platform. Positions the tool within the broader Azure ecosystem.
Lesson 5 • Workspace Setup and Navigation
Guides students through provisioning an Azure Databricks workspace and exploring its UI. Builds the hands-on foundation needed for all subsequent labs.
Chapter 2HideHide detailsSee detailsApache Spark Core Concepts in Databricks
Apache Spark Core Concepts in Databricks
Lesson 1 • Spark Performance Fundamentals
Introduces partitioning, caching, and broadcast joins as primary performance levers. Students apply these techniques to reduce job execution time.
Lesson 2 • Spark Architecture and Execution Model
Explains drivers, executors, tasks, and stages to demystify how Spark distributes work. Provides the mental model needed to write and debug efficient Spark jobs.
Lesson 3 • DataFrames and the Spark API
Teaches the DataFrame API for structured data manipulation using Python and SQL. Covers transformations, actions, and lazy evaluation as core Spark concepts.
Lesson 4 • Spark SQL and Temporary Views
Enables SQL-based data querying within Spark using temporary views and catalog tables. Bridges SQL skills with the Spark execution engine.
Lesson 5 • Reading and Writing Data Sources
Covers reading from and writing to common formats including CSV, JSON, Parquet, and Delta. Students connect Spark jobs to real storage backends.
Chapter 3HideHide detailsSee detailsDelta Lake and Data Reliability
Delta Lake and Data Reliability
Lesson 1 • Delta Table Optimisation
Covers OPTIMIZE, Z-ordering, and VACUUM commands to maintain Delta table performance. Students apply maintenance routines to production-grade tables.
Lesson 2 • Creating and Managing Delta Tables
Covers creating Delta tables from DataFrames and SQL, including managed and external tables. Students perform inserts, updates, and deletes on Delta tables.
Lesson 3 • Merge, Upsert, and CDC Patterns
Teaches the MERGE INTO command for upsert logic and change data capture patterns. Connects Delta capabilities to real-world incremental data ingestion needs.
Lesson 4 • Time Travel and Versioning
Demonstrates querying historical table versions and restoring prior states using Delta time travel. Enables audit, rollback, and reproducibility workflows.
Lesson 5 • Delta Lake Architecture and Benefits
Explains the Delta log, ACID guarantees, and how Delta Lake solves common data lake problems. Sets the context for all Delta-based operations in the chapter.
Chapter 4HideHide detailsSee detailsData Ingestion and ETL Pipelines
Data Ingestion and ETL Pipelines
Lesson 1 • Batch Ingestion Patterns
Covers full and incremental batch ingestion strategies from cloud storage and databases. Students implement watermark-based and partition-based incremental loads.
Lesson 2 • Orchestrating Pipelines with Databricks Workflows
Covers building multi-task workflows using Databricks Jobs to schedule and orchestrate pipelines. Students configure dependencies, retries, and alerting.
Lesson 3 • Delta Live Tables for Declarative Pipelines
Introduces Delta Live Tables (DLT) as a declarative framework for building reliable ETL pipelines. Students define streaming and batch tables with quality expectations.
Lesson 4 • Transformation Logic and Data Quality
Teaches applying business transformation rules and enforcing data quality constraints in pipelines. Students use Spark functions and Delta constraints to validate data.
Lesson 5 • Auto Loader for Streaming Ingestion
Introduces Auto Loader as a scalable, fault-tolerant mechanism for ingesting new files automatically. Connects file-based ingestion to structured streaming concepts.
Chapter 5HideHide detailsSee detailsStructured Streaming and Real-Time Data
Structured Streaming and Real-Time Data
Lesson 1 • Structured Streaming Fundamentals
Explains the continuous query model, micro-batch processing, and the streaming DataFrame API. Establishes the conceptual foundation for all streaming labs.
Lesson 2 • Stateful Streaming and Windowing
Teaches windowed aggregations, watermarking, and stateful operations for time-based analytics. Enables students to compute rolling metrics over event streams.
Lesson 3 • Writing Streaming Output to Delta Lake
Demonstrates writing streaming query results to Delta tables with checkpointing and fault tolerance. Connects streaming processing to durable, queryable storage.
Lesson 4 • Reading from Streaming Sources
Covers connecting to Event Hubs, Kafka, and file-based streaming sources in Databricks. Students configure source options and manage offsets.
Lesson 5 • Monitoring and Debugging Streams
Covers streaming query progress, metrics, and common failure patterns in production streams. Students use Databricks UI and logs to diagnose streaming issues.
Chapter 6HideHide detailsSee detailsUnity Catalog and Data Governance
Unity Catalog and Data Governance
Lesson 1 • Data Lineage and Auditing
Demonstrates capturing column-level lineage and audit logs through Unity Catalog. Enables students to trace data origin and access history for compliance.
Lesson 2 • Access Control and Permissions
Covers granting and revoking privileges on catalogs, schemas, tables, and views using SQL. Students implement least-privilege access patterns for data assets.
Lesson 3 • Data Discovery with the Databricks Catalog
Covers tagging, searching, and documenting data assets using the Databricks data catalog UI. Improves data discoverability and self-service analytics across teams.
Lesson 4 • Unity Catalog Architecture
Explains the three-level namespace, metastore, and how Unity Catalog unifies governance across workspaces. Provides the structural foundation for all governance configurations.
Lesson 5 • Managing External Data and Volumes
Teaches registering external locations, creating volumes, and managing non-tabular data assets. Extends governance to files and unstructured data in cloud storage.
Chapter 7HideHide detailsSee detailsMachine Learning with Databricks and MLflow
Machine Learning with Databricks and MLflow
Lesson 1 • Training Models with Spark and scikit-learn
Covers training single-node and distributed models using scikit-learn and Spark MLlib. Students apply cross-validation and hyperparameter tuning at scale.
Lesson 2 • Experiment Tracking with MLflow
Teaches logging parameters, metrics, and artefacts with MLflow Tracking for reproducible experiments. Students compare runs and identify the best-performing model.
Lesson 3 • MLflow Model Registry and Lifecycle
Covers registering models, managing versions, and transitioning models through staging and production. Implements a governed model promotion workflow.
Lesson 4 • Model Serving and Batch Inference
Demonstrates deploying models as REST endpoints and running batch inference on Delta tables. Connects trained models to downstream data and application consumers.
Lesson 5 • Databricks ML Runtime and Feature Engineering
Introduces the ML Runtime environment and Databricks Feature Store for reusable feature pipelines. Establishes the ML development environment for subsequent sections.
Chapter 8HideHide detailsSee detailsProduction Deployment and Platform Operations
Production Deployment and Platform Operations
Lesson 1 • Security and Network Configuration
Teaches securing Databricks with private endpoints, VNet injection, and secrets management. Students apply defence-in-depth principles to the platform.
Lesson 2 • Disaster Recovery and High Availability
Covers workspace backup strategies, multi-region deployments, and recovery runbooks. Students design resilient architectures for business-critical workloads.
Lesson 3 • Monitoring, Logging, and Alerting
Demonstrates integrating Databricks logs with Azure Monitor and setting up proactive alerts. Students build observability into production pipelines.
Lesson 4 • CI/CD for Databricks Workloads
Covers integrating Databricks with Git providers and building automated test and deploy pipelines. Students implement a full CI/CD workflow for notebooks and jobs.
Lesson 5 • Cost Management and Cluster Optimisation
Covers monitoring DBU consumption, right-sizing clusters, and using spot instances to reduce costs. Students build cost-aware cluster policies for their organisation.

Your valid completion certificate
This course is for you:
Data analysts ready to transition into a data engineering role.
Cloud engineers expanding their skills into big data processing.
SQL developers who want to work with distributed data at scale.
Software engineers building their first production data platform.
BI developers seeking deeper control over their data pipelines.
Data science graduates entering industry with real-world tooling needs.
What our students say
Hear from those who've already studied with us:
Your lessons are perfect. I purchased the one-year package and finally have the opportunity to follow various topics of interest without needing to change platforms... I'm grateful for everything you do, I've already recommended you to other people...
I like how the lessons are straight to the point and how I can change chapters and skip content I don't need.
I like the content and the way videos are presented and transcribed, which speeds up the process!
The platform is fast and simple to use. The diversity of content and complementary videos really help with learning.
Top upskilling courses




FAQ
Who is Elevify? How does it work?
Do the courses have certificates?
Are the courses free?
What is the course workload?
What are the courses like?
How do the courses work?
What is the duration of the courses?
What is the cost or price of the courses?
What is an EAD or online course and how does it work?
PDF Course